Simeon Nedelchev

Simeon Nedelchev

Researcher & Senior RL Engineer Articulated Robots RL Hybrid Methods Sim-to-Real Motion Imitation

I build control for articulated robots — from novel actuators to legged locomotion, reinforcement learning, whole-body control, and sim-to-real deployment. Currently exploring generative motion planners stacked on unified whole-body controllers.

  • Researcher & Senior RL Engineer — Institute of Artificial Intelligence, MIPT
  • Senior Lecturer — Innopolis University (robotics, control, simulation)
  • Ph.D. in Computer Science (Robotics), Innopolis University
  • ~9 years robotics — research, prototyping, industry, teaching (Innopolis, Korea, Sber, MIPT)
  • ~4–5 years RL & deep learning for robotics · 3+ years locomotion & WBC in production/research stacks

M.Sc. — Korea University of Technology and Education · STANKIN

simkaned@gmail.com · simeon-ned.github.io · GitHub · X · Google Scholar

Experience & Technical Profile

Humanoid RL & WBC · industry + research · sim-to-real on real hardware

Career

2026–now Senior RL Engineer · MIPT
Humanoid RL, WBC, generative motion research
2023–2026 Senior RL Engineer · Sber Robotics
Green humanoid — predictor-based locomotion, WBC, teleop, actuator sys ID, sim-to-real (AIJ 2025)
2022–now Senior Lecturer · Innopolis University
Robotics, nonlinear control, simulation
2019–2023 Researcher · Innopolis University
Novel actuators, adaptive control, hardware prototyping
2017–2019 Research Assistant · BioRobotics Lab, Korea
Mechanical design, embedded control, robot prototyping

~9 yrs robotics · ~4–5 yrs RL/DL · 3+ yrs locomotion & WBC in production & research

What I deliver

  • Articulated robots — humanoids, WBC, locomotion
  • RL & hybrid methods — learning + model-based / generative stacks
  • Sim-to-real — train in sim, deploy on hardware
  • Motion imitation — tracking, retargeting, multi-clip RL

How I work

RL training
PPO-style pipelines · mjlab · Isaac Lab · motion priors & libraries
Sim-to-real
Reward shaping · domain randomization · curriculum · multi-clip training · on-robot eval
Simulation
MuJoCo · MJX · MuJoCo Warp · Isaac Sim/Lab · Genesis
ML stack
PyTorch — training & deploy · JAX — research & differentiable sim
Tooling
Python · C/C++ · Bash · LaTeX · Docker · uv

WBC-Gen

Generative Flow matching Gen → WBC Unitree G1

Reactive Generative Motion Planner for Unified WBC

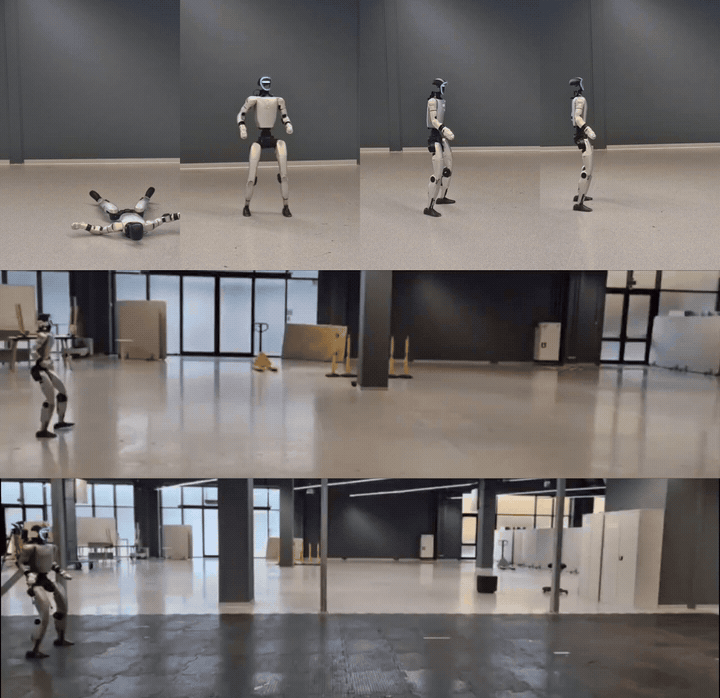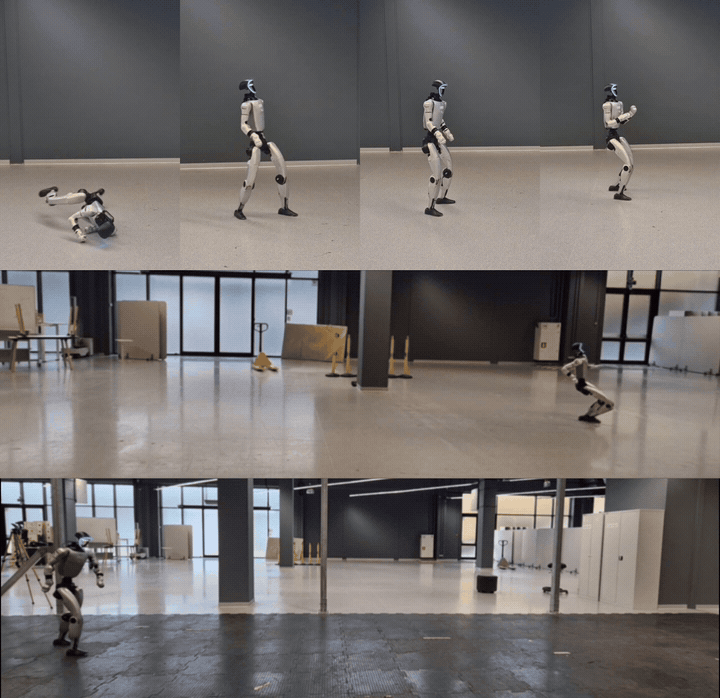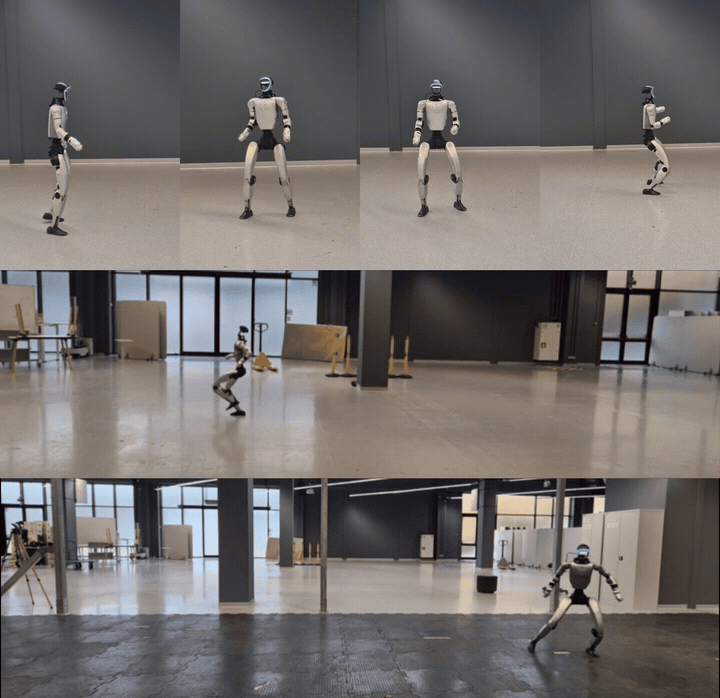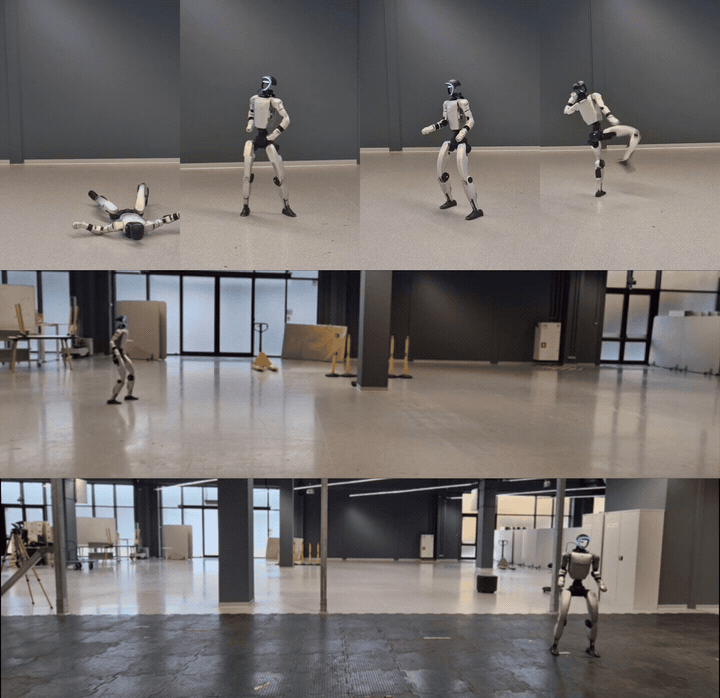
Walking on G1
Disturbance recovery

Fast, task-general Gen → trackable WBC references every step above a frozen controller.

Latent flow matching trained from streaming WBC rollouts with domain randomisation — reactive, physics-aware and controller-aware generation, not open-loop kinematic playback. Generalizable across tasks under one unified WBC contract; recovery and get-ups from failed states are embedded in the planner ((sim: autonomous recovery & get-up), with no fall/stand mode FSM. On G1 CPU (no Jetson): walk / sprint teleop, disturbance rejection, and agile recovery. Try Gen alongside WBC tracking to interactively generate robot locomotion (WASD to steer, Shift to sprint; G switches clips ↔ Gen). Training code and paper coming soon.

  • Fast / onboard — Gen + WBC co-located on G1 CPU (no Jetson)
  • Task-general — stack generators under one unified WBC contract
  • Autonomous recovery — get-ups from failed states without a mode FSM
Stack
Control Operators–style flow · mjlab / MuJoCo Warp · ONNX deploy
Status
Deploy code available · training code & paper coming soon

WBC-Mjlab

RL Motion tracking BeyondMimic / ZEST / SONIC Sim-to-real

Whole Body Control in MuJoCo Lab

WBC-Mjlab Unitree G1 hardware collage: get-up recovery and walking
G1 hardware — get-up recovery & multi-scene walking

One shared MDP → train once, deploy one policy for many whole-body skills.

Modular mjlab stack — shared MDP in env/, registered robot entities, presets that compose tasks without forking core code. Multi-clip motion tracking with BeyondMimic / ZEST / SONIC-style task presets.

  • Tasks, not forks — ZEST, BeyondMimic-style RSI, deploy obs as --task on one CLI & log layout
  • Multi-motion — clip-library training; one policy generalizes across skills at runtime
  • Plug-in robots — extension packages via register_wbc_extension
  • Sim → real — train/play exports policy.onnx + config.yaml for deploy runtimes
Stack
mjlab · MuJoCo · PPO-style RL
Output
policy.onnx + config.yaml deploy export · open-source framework

PSM

RL locomotion Sim-to-real Unitree G1

Predictive Style Matching for Natural Locomotion
PSM walking on hardware
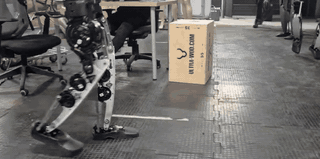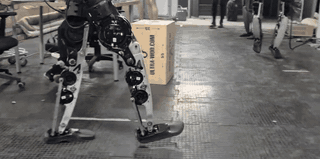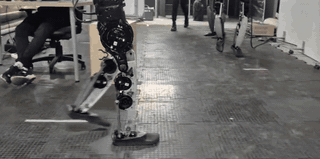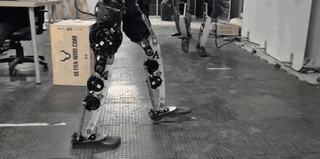
Natural walking on Unitree G1
PSM disturbance recovery
Push recovery & robustness

Predictive Style Matching — natural gait without imitation fragility on Unitree G1 (sim & hardware).

Task-only RL transfers and recovers well, but gaits stay stiff; clip tracking looks more natural yet references fight the balance controller — about 5× more falls under pushes. A frozen predictor fφ maps lower-body history and commands to state-conditioned upper-body and gait targets; matching rewards are used only at training time — the deployed πθ keeps vanilla proprioceptive observations.

  • Stage 1 — supervised fφ on retargeted walking (GRU–MLP, reconstruction + symmetry); frozen
  • Stage 2 — PPO + predictive matching rewards; locomotion-first curriculum; export πθ only
  • Deployment — same inference cost as task-only RL; no clip phase, reference pose, or predictor on hardware
  • Results — ~8× lower upper-body DTW vs vanilla RL; fall rate within 1σ; tracking lowest style error but ~5× more falls
Role
Lead author · ~99% implementation & experiments
Stack
MuJoCo · PPO · retargeted walking corpus · Unitree G1 deploy
Paper
Nedelchev et al. · arXiv:2606.07083 · 2026

Sber Green Humanoid

Industry RL · WBC Teleop AIJ 2025

RL Locomotion & Whole-Body Control

Zero-shot dance tracking
Zero-shot dance
Teleoperation WBC
Teleoperation WBC
Object catch with WBC
Object catch
Natural RL locomotion

Senior engineer — RL locomotion & WBC on the Green humanoid (AIJ 2025).

Predictor-based human-like locomotion; unified WBC for teleoperation, dance, and zero-shot skills; synthetic references without mocap retargeting; motor and actuator system identification for simulation fidelity.

  • End-to-end: training → control stack → on-robot demos
  • Predictor-guided natural walking
  • One WBC policy for teleop & skills — trained on synthetic data
Role
Senior engineer · Sber Robotics Center (2023–2026)
Stack
Isaac Lab · MuJoCo sim · custom model assembly · PPO-style RL · actuator sys ID · custom control stack

mink-warp

Open source MuJoCo Warp GPU IK

Batched Differential IK on MuJoCo Warp

Cassie — closed-chain equality constraints (GPU ADMM)

GPU-parallel IK on MuJoCo Warp — author, PyPI package.

Mink-shaped API for batched task-space IK: closed chains, hard limits via GPU ADMM, CUDA graphs for real-time loops.

  • Complements RL/WBC stack — fast IK for sim and teleop
  • Panda, Cassie, G1 reference examples
Role
Author · PyPI package
Built on
MuJoCo Warp · Mink API shape

Open Source

Dynamics · system ID · differential IK · retargeting · GPU-accelerated control

  • Pinocchio — rigid-body dynamics, inertia parametrizations
  • Pink — differential IK for Pinocchio
  • Mink — MuJoCo port; EqualityConstraintTask for closed chains
  • mink-warp — author; batched IK on MuJoCo Warp
  • GMR — SOMA BVH format, multi-robot configs
  • mujoco-sysid — contributor; system ID in MuJoCo & MJX — parameter estimation, dynamics regressors
  • MJINX — co-author; differentiable GPU IK (JAX + MJX)

Motivation & Fit

Why this work · what I bring · where I'd take it next

What motivates me

The synergy of interesting problems that are practical and research-worthy at once — pushing what robots can execute, from agile locomotion and whole-body motion to generative motion planning beyond fixed gaits, with research and production moving together.

  • Teams that keep up with SOTA and ship on real robots
  • Scalable RL, rigorous evaluation, hardware-ready policies
  • Newer robot platforms · publications & collaborations

Expertise & why I'm a fit

Industry + research on learning-based control. At Sber Robotics: core senior RL engineering — predictor-based locomotion, WBC, actuator sys ID, MuJoCo pipelines to deployable policies. Research & teaching: WBC and generative motion planning.

Directions I'd explore

  • Score motion priors + WBC — enhance WBC tracking and naturalness with reusable SMP score-matching motion priors (Mu et al., 2025)
  • Reflex layer via SMP — train a policy with SMP score-matching that modifies the nominal WBC reference under disturbance while staying in distribution — autonomous get-ups after falls, push recovery — not end-to-end VLA
  • Physically consistent generation — roll out generative datasets through WBC rollouts in sim and train generators in the same loop; feasible on relatively small-memory GPUs
  • Data-driven estimators on WBC rollouts — train state and contact estimators from WBC simulation rollouts — physics-consistent labels at scale for deployable perception stacks
  • Online & state-conditioned generation — streaming motion from robot state, velocity commands, and sparse kinematic goals; ARDY-style autoregressive diffusion with waypoints and keyframes, wired into WBC tracking
  • Building generators — modular real-time motion stacks like MotionBricks; improve online/offline naturalness in RL and planning with score-matching motion priors

Thank you

Happy to discuss humanoid RL, WBC, and sim-to-real for your team.

simkaned@gmail.com · Telegram · simeon-ned.github.io · X · CV

Questions?